What is MLOps for LLM and SI systems?
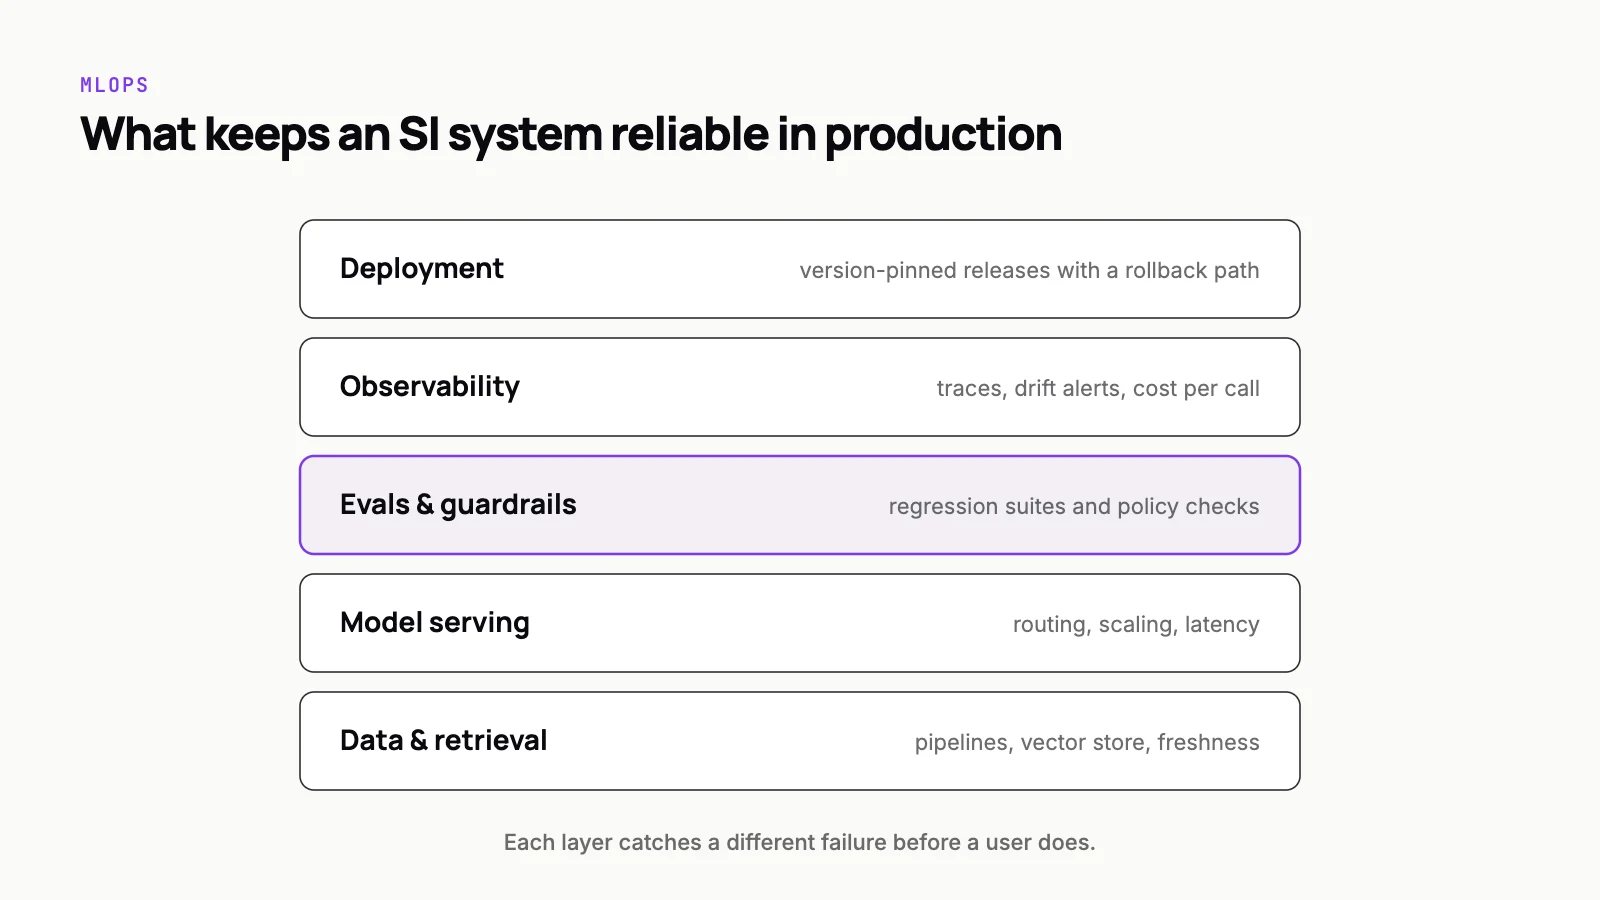
MLOps for LLM and SI systems is the infrastructure and practice that keeps models dependable, affordable and auditable once real traffic arrives. It covers six areas. Model serving runs inference on managed endpoints or self-hosted servers such as vLLM or Triton, with autoscaling, tail-latency targets, GPU cost control and blue-green deploys. Retrieval infrastructure covers vector stores, embedding pipelines and hybrid search. Eval pipelines score every model, prompt or data change in CI and block deploys that regress. Drift monitoring tracks outputs and embeddings statistically and alerts when behaviour moves away from the launch baseline. Observability logs token cost, latency, prompts and responses, and keeps an audit trail of what the system said and when. Data pipelines keep vector stores and fine-tuning datasets fresh through batch or streaming jobs. Teams that skip these layers usually learn about problems from users: quality fades without an error, costs climb unpredictably, and auditors ask for records nobody kept.