Book a consult
Services

Production SI, engineered end to end, six eval-gated service lines.

Visit Services →
Solutions

The same playbook, tuned to the constraints of the sectors we ship into most.

Visit Solutions →
Live Projects

Proof, not promises, selected case studies and recognition.

Visit Live Projects →
How we work

A transparent, 3-phase playbook from first audit to embedded team.

Visit How we work →
Studio

The senior team behind the work, and how to reach us.

Visit Studio →
octalcode
Services
Solutions
Live Projects
How we work
Studio
● OCTALCODE · INFINITE SOLUTIONS · ONE AGENCYBook a consult ↗

SI-Driven QA

Break it in staging, not in production.

A silent model regression reaches your customers, and your brand, before it reaches your dashboard. We build the eval suites, adversarial red-teaming, and drift monitoring that catch failures in staging, protecting both revenue and reputation.

01 · QA capabilities

Six QA disciplines.

Traditional QA catches code bugs. SI QA catches model regressions, safety failures, and retrieval drift. We cover both with the same rigour.

01 · Discipline

LLM Eval Suites

Custom evaluation harnesses measuring accuracy, hallucination rate, factual consistency, and toxicity on your specific domain and queries, not generic benchmarks.

02 · Discipline

Regression Testing

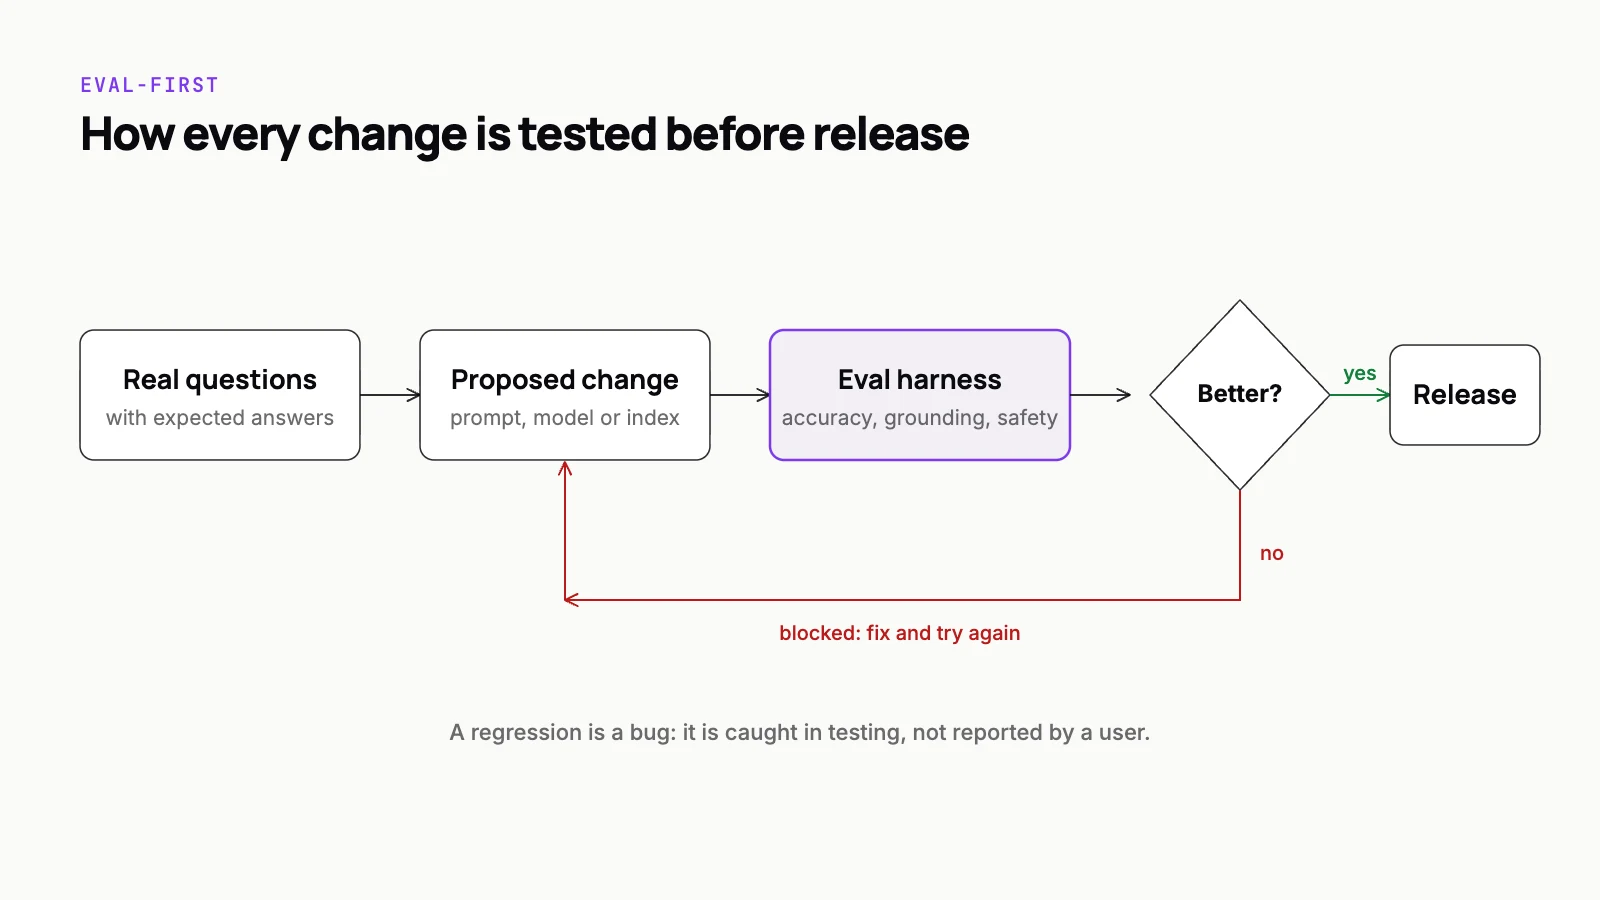
CI-integrated test suites that run on every model version change. A regression in eval score blocks the deploy, protecting users automatically.

03 · Discipline

Red-Teaming

Adversarial prompt testing to find injection vulnerabilities, jailbreak paths, and safety failures before they reach production or a press story.

04 · Discipline

RAG Quality Audits

Context relevance, faithfulness, and answer completeness testing across your retrieval pipeline. We find where your RAG system hallucinates and fix it.

05 · Discipline

Drift Monitoring

Statistical monitoring of live model outputs against your eval baseline. Automated alerts when output quality drifts, before users notice.

06 · Discipline

Load & Latency Testing

Throughput and P95/P99 latency testing under realistic production load. We find the breaking point before your users do.

Straight answers

The short version.

How do you test an LLM application before release?

You test an LLM application before release with a domain-specific eval suite that runs automatically on every change, plus adversarial, retrieval and load testing. Build the eval set from real queries in your domain, each with an expected answer or scoring rule, and measure accuracy, hallucination rate, factual consistency and toxicity rather than relying on generic benchmarks. Wire it into CI so a lower score after any prompt, model version or retrieval change blocks the deploy, the same way a failing unit test would. Providers update models often, so this regression gate matters as much as the first run. Add red-teaming for prompt injection, jailbreaks and data leakage. If the application uses RAG, audit context relevance, faithfulness and completeness separately to find where answers drift from their sources. Run throughput and tail-latency tests under realistic load to find the breaking point. After launch, compare live outputs against the eval baseline so quality drift raises an alert before users notice.
What is red-teaming for LLM applications?

Red-teaming for LLM applications is structured adversarial testing: deliberately attacking a model-powered system to find the ways it can be made to misbehave before real users or attackers do. Testers write and automate hostile inputs that target known failure classes. Prompt injection tries to override instructions, including text hidden in documents, web pages or tool results that an agent reads. Jailbreaks try to talk the model past its safety rules. Leakage tests probe for exposure of the system prompt, other users' data or personal information. Agent tests check whether tool calls can be steered into actions the user never asked for. Domain tests look for biased or unsafe answers and for refusal failures, where the model either refuses valid requests or complies with harmful ones. Each finding should be documented with a reproduction, a severity rating and a remediation plan, then turned into a scored test case so the fix stays fixed in every later release.

Diagram of an eval-first release loop: real questions with expected answers and a proposed change to the prompt, model or index go through an eval harness for accuracy, grounding and safety; only a change that scores better is released, otherwise it is blocked and fixed.
Every change is tested against real questions before release.
The Tower (35 s): duplicated code is up 81% and error masking up 47% since SI coding took off (GitClear, 623M code changes, 2023 to 2026). Watch on YouTube

02 · Eval-first engineering

Why evals come before code.

  1. Define the target, then build to it

    An eval suite written before the build defines what "working" means. Without it, you're shipping by vibes and calling it done when the demo looks good.

  2. Catch regressions across model versions

    LLM providers update models frequently. What passed on GPT-4o last quarter may fail today. CI-integrated evals catch this automatically.

  3. Make safety measurable

    Safety is not a policy document. It's a set of scored test cases: adversarial prompts, PII leakage attempts, and refusal failure modes. We make it measurable.

  4. Build stakeholder confidence

    Regulated industries and enterprise clients want proof, not promises. Eval reports give your stakeholders the evidence they need to approve SI in production.

Proof, not promises

Twenty-plus SI systems shipped to production. One playbook, six industries, and a team that stays past launch.

SI systems live in production
20+
Senior engineers & researchers
21+
Upwork rating, 3 verified reviews
5.0
Founded in Lahore
2022
Verified Upwork clientSI product engagement · 5-star review

03 · Common questions

Before you brief us.

What is an LLM eval and why do we need one?
An LLM eval is a scored test suite that measures how well your model performs on your specific use-case, not a generic benchmark. Without evals, you have no way to know if a model update made things better or worse. We treat failing evals the same as failing unit tests: they block deploys.
What does red-teaming actually find?
Prompt injection vulnerabilities, system prompt leakage, jailbreak paths, bias in domain-specific responses, PII exfiltration risks, and model refusal failure modes. We document every finding and provide a remediation plan.
Can you audit a RAG pipeline we already built?
Yes. We run RAGAS and custom evals against your retrieval pipeline, identify the query types where faithfulness and relevance are lowest, and propose chunking, reranking, or retrieval strategy changes to fix them.
How do you set up continuous evals?
For an existing LLM application we start with a basic eval pipeline in your CI. We connect it to your existing CI provider and set threshold alerts on day one.

Available for new engagements

Ready to make your SI provably safe?

30 minutes, one of our seniors, no slide deck. By the end of the call you will know whether we are the right team, and if not, who is.

Or call +1 (512) 710-5701

Let's scope it.Instant answers · free project scoping